Agentic AI is only as good as the data foundation beneath it
The more autonomous AI agents become, the more identity, reliable data and context matter. Why an AI strategy without a data strategy is incomplete.
Recently, an incredible amount of attention has been focused on agentic AI within companies. Organizations are building AI agents, remodeling processes, linking systems together, and investigating which tasks can soon be partially or fully performed by AI. The emphasis is primarily on making and experimenting. There is building, testing, adjusting, and rebuilding.
That is logical in itself. The possibilities of agentic AI are great, and the technology is developing rapidly. At the same time, this creates a risk that a much less sexy but at least as important subject fades into the background: the data foundation on which all that AI must function.
Because no matter how good an AI agent is, ultimately that agent has to get its information from somewhere. If the underlying data is incorrect, scattered across dozens of systems, or cannot be unambiguously linked to the same customer, a fundamental problem arises. You can then build a particularly intelligent agent, but that agent still operates on top of a fragmented reality.
Garbage in, garbage out is no longer the whole story
We have known the principle of garbage in, garbage out for decades. If you put bad information into a system, you can hardly expect reliable results.
With agentic AI, the problem goes further than that. It is no longer exclusively about whether individual data is correct. Increasingly important is the question of how data from different parts of the organization is brought together and how an AI agent can understand which information belongs together.
For example, many organizations have multiple databases containing data about the same customer. In the CRM, someone has a customer number, in the marketing platform that person is recognized by an email address, and in the billing system, there is another account number. The customer service platform might contain an old phone number, while the e-commerce platform contains the most current contact details.
The data itself doesn't even have to be wrong. The problem is that no one, and therefore also not the AI agent, automatically knows that all those records are about the same person.
That is precisely where the data foundation becomes crucial.
The most important question is increasingly: who are we actually talking about?
When organizations seriously start working with agentic AI, the way they have to look at data changes. It is no longer just about the question of what information is available, but especially about the question of who or what is behind that information.
Suppose a customer contacts an organization. An AI agent must then be able to determine who that customer is, what products they use, what previous contacts there have been, what agreements have been made with them, and what information is currently up to date.
That sounds simple, but within many organizations, that is anything but self-evident.
One department works with a CRM, another with an ERP system, and yet another with its own service platform. In addition, there are data warehouses, marketing tools, e-commerce platforms, document management systems, and sometimes all kinds of local databases or Excel files.
All those systems contain pieces of the same reality.
An employee who has worked at an organization for ten years often knows exactly where to look. They know that address data in system A is usually reliable, that contract information must come from system B, and that information in system C is regularly outdated.
An AI agent does not have that implicit knowledge automatically.
You have to make that knowledge explicit.
One customer can have ten different identities in an organization
That makes identity resolution an increasingly important part of the data foundation for agentic AI. Identity resolution essentially revolves around one question: which records, accounts, and identifiers actually belong to the same person or organization?
For example, a customer may be registered in one system with a private email address and in another system with a business email address. There may also be a phone number, a customer number, and a user account. When these different identifiers are not properly linked to each other, an AI agent may think it is dealing with multiple people.
The opposite problem can, of course, also arise. Two people may use the same address or have a shared email address, causing a system to incorrectly conclude that they are the same person.
These types of problems already existed before generative AI became popular. The difference is that the consequences become greater when AI not only presents information but also performs actions independently.
If an employee sees different records, they can still doubt, check, and correct. An autonomous agent must take a decision at some point.
The more autonomous AI becomes, the more important reliable identification thus becomes.
Customer 360 gets a new meaning through agentic AI
The idea of Customer 360 is also not new. Organizations have been trying for years to build as complete a picture of their customers as possible by combining data from different sources.
For a long time, Customer 360 was primarily seen as a tool for marketing, personalization, and analytics. If you had a better picture of the customer, you could create more relevant campaigns and perform better segmentations.
Agentic AI changes that.
A complete picture of the customer is increasingly becoming part of the operational infrastructure of an organization. When an AI agent communicates with a customer on behalf of a company, solves a problem, or prepares a decision, that agent must be able to understand who they have in front of them.
In this regard, not only historical information is important. Context also plays a role. Which products does this customer use? Which service questions have they asked before? Is there already a complaint being processed? Was there perhaps contact with an employee yesterday? Have agreements been made that the agent should be aware of?
Without that coherence, a situation arises where an agent can technically be very intelligent but operates quite stupidly organizationally.
Data orchestration therefore becomes more important than ever
Therefore, in addition to data quality, data orchestration is also becoming increasingly important.
Data orchestration is about organizing, connecting, and making data from different systems available at the right time. Instead of just storing information, an organization must be increasingly able to determine which data is needed in which situation and how that data can be brought together safely and reliably.
This does not automatically mean that all information must be placed in one giant central database.
Agentic AI precisely makes another way of working possible.
An agent can consult different systems at the moment information is needed, collect data, and temporarily create a complete picture from it. The agent does not necessarily have to move all data permanently to one central platform for this.
That can mean a fundamental change in the way organizations design their data architecture.
Where organizations traditionally often tried to get all information in one place first, in an agentic architecture it can revolve much more around dynamically composing context.
The agent as an intelligent octopus
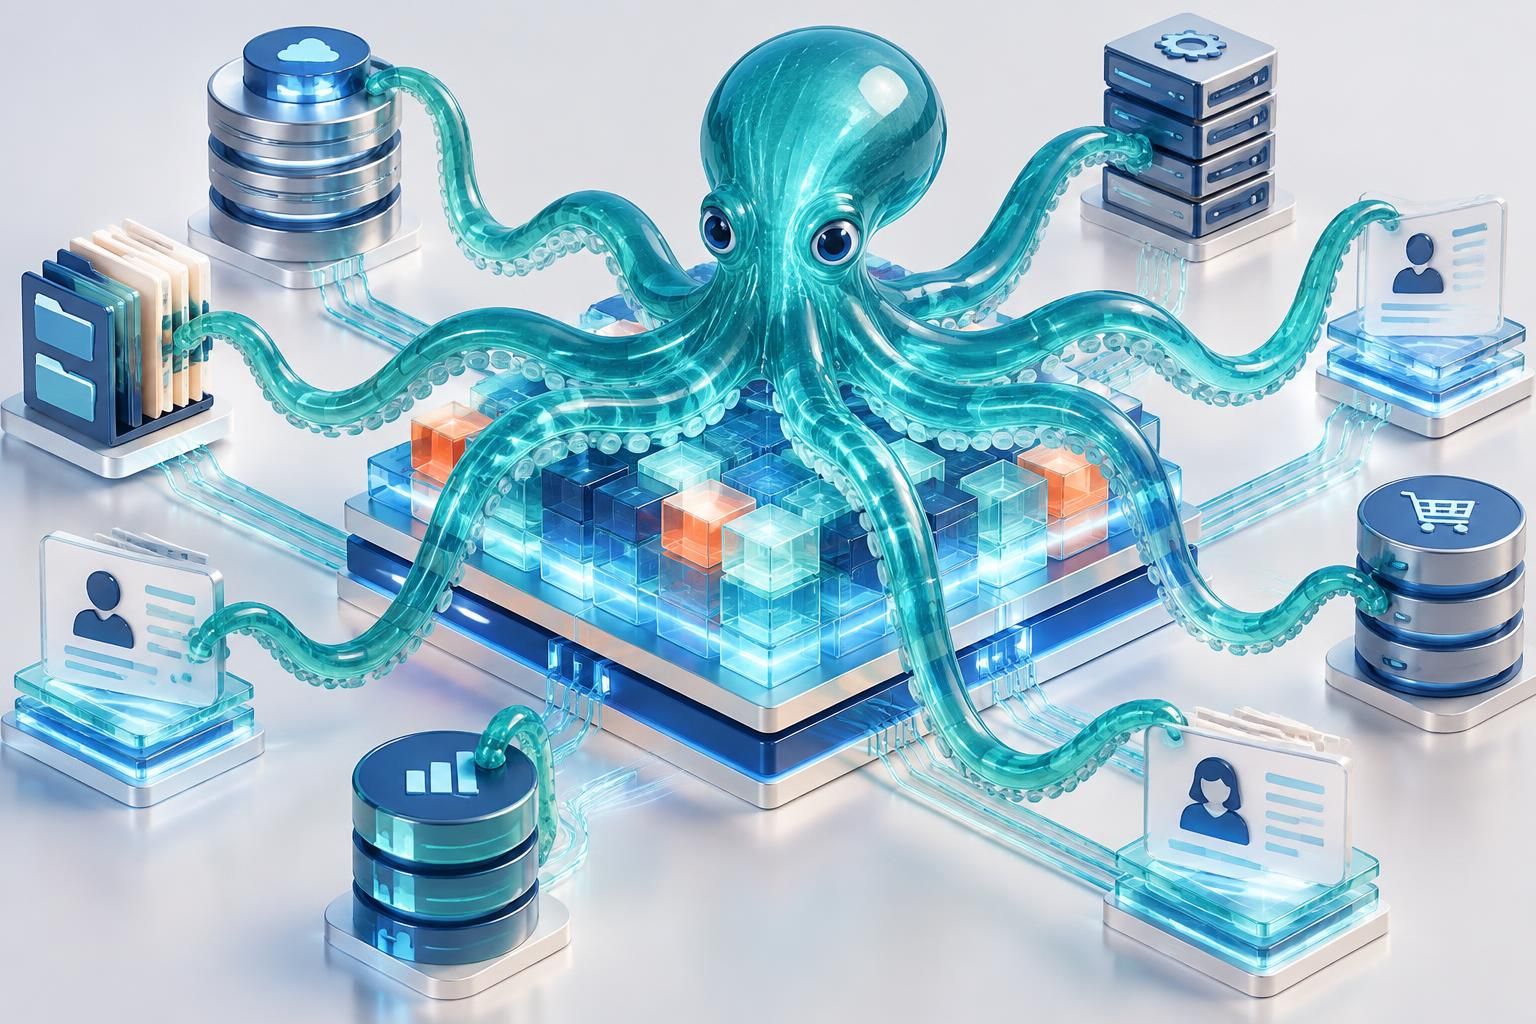
In that respect, you can compare an AI agent to an intelligent octopus.
The different tentacles of that octopus can connect with different systems within the organization. One tentacle retrieves customer data from the CRM, another looks at recent invoices, a third retrieves the most recent service notifications, and yet another checks contract information.
Then the agent brings all that information together and tries to make one coherent picture of it.
That is exactly why agentic AI does not only have to be dependent on a strong data foundation, but at the same time can also play a role in better utilizing existing data.
For example, an agent can recognize that data from different systems likely belongs to the same customer. It can signal deviations, recognize missing information, and compare different sources.
This makes the agent not only a user of data, but also an orchestrator of data.
And that is exactly what makes agentic AI interesting.
From one central database to dynamic context
For years, there was much emphasis on centralization within data architecture. Organizations built data warehouses, data lakes, lakehouses, and customer data platforms with the idea that as much information as possible had to be brought to one central place.
That model remains valuable in many cases, but agentic AI also makes another architecture possible.
Not all information necessarily has to be physically in the same place, as long as an agent can reliably determine where the right information is to be found and how it should be combined.
That shifts the focus from static data to dynamic context.
An AI agent, for example, does not need to know the entire customer database. It must be able to determine at the right time which information is relevant for this specific customer, in this specific situation, and for this specific task.
That is a much more contextual way of working.
The question therefore changes from: 'Where do we store all the data?' to: 'How do we ensure that an agent can compose the right context at any time?'
That may seem like a subtle difference, but architecturally it is a massive shift.
Yet AI cannot determine the truth on its own
That is also where the limit lies.
AI is very good at recognizing patterns. An agent can see that two names are very similar, that two records contain the same phone number, or that different accounts likely belong to the same organization.
But ultimately, a company still has to determine when something is considered the truth.
For example, which source is leading when two systems show a different address? What happens if the CRM says a customer is active, while the billing system shows the contract was terminated three months ago? Which information may be automatically merged and when is human control necessary?
Those kinds of questions cannot be entirely left to a language model.
An organization must determine for itself which systems are leading, which data may be used, which rules apply in case of conflicts, and how decisions can be audited afterwards.
That is data governance.
And especially in a world of agentic AI, good governance is becoming increasingly important.
A good data foundation therefore goes much further than clean databases
When people talk about a good data foundation, they often think primarily of data quality. Is the data complete? Are fields correctly filled in? Are there no duplicate records?
That remains important, but for agentic AI, it is only part of the story.
A good data foundation also means it is clear who a customer is, which identifiers belong to them, and which information from different systems can be linked to the same person.
In addition, it must be known which data source is leading. For instance, an organization must determine from which system an agent should retrieve the official address, the current contract status, or the most recent payment information.
It must also be clear where information comes from. When an agent makes a decision or gives advice, you want to be able to understand on the basis of which data that happened.
Then there is authorization as well. Just because an agent can technically access information does not mean it is allowed to use that information in every situation.
A good data foundation, therefore, consists of more than just data. It consists of identity, context, reliability, access, governance, and traceability.
From single source of truth to system of context
Organizations have been talking about creating a *single source of truth* for years. The idea is that there is one authoritative source for important information.
That principle remains valuable, but in the world of agentic AI, it may not be sufficient.
An agent often does not need a single truth, but a complete context.
When a customer makes contact, that context can consist of CRM information, contract details, recent transactions, previous communication, product usage, and open service tickets.
No single source necessarily contains the full story.
Therefore, alongside the *single source of truth*, a new concept may be emerging: the *system of context*.
An infrastructure that not only determines where information is located, but that can assemble the right context around a person, organization, process, or decision at any moment.
That is likely one of the most important architectural questions of agentic AI.
Why successful AI demos sometimes stall in practice
The importance of that foundation often only becomes visible when an organization tries to move from a pilot to production.
An AI demo is relatively easy to control. You work with a clear use case, a limited amount of data, and a small number of systems. Exceptions are manageable, and the context is often carefully prepared.
The reality of a large organization looks very different.
There, duplicate customer records, outdated data, missing fields, and different definitions of the same concept exist. There are legacy systems, historical databases, manual corrections, and exception processes that are not formally documented anywhere.
People have learned over the years how to handle this.
An AI agent still has to learn that.
And precisely there, it often turns out that the problem is not the intelligence of the AI model, but the quality and coherence of the underlying organizational data.
The next phase of agentic AI is about trust
The first phase of generative AI was mainly about wonder. People discovered that AI could write, code, summarize, and analyze.
The next phase was about application. Companies started building copilots, automating processes, and integrating AI into existing software.
With agentic AI, we are now entering a new phase.
In this phase, it is increasingly less about whether AI can do something and more about whether we can trust AI to do something independently.
That difference is enormous.
When an AI system only generates a draft text, the user remains responsible for the final decision.
When an AI agent independently changes an order, answers a customer, processes a file, or prepares a payment, the quality of the underlying information suddenly becomes business-critical.
The more autonomous the agent becomes, the more important the data foundation.
AI strategy without a data strategy is therefore incomplete
Many organizations now have an AI strategy. They create roadmaps, select use cases, experiment with models, and build platforms on which various agents can run.
But alongside every AI roadmap, there should actually be a data roadmap.
Not just with the question of how much data is available, but especially with the question of whether an agent can actually understand and trust that data.
Can we recognize the same customer when they appear in five systems? Do we know which information is leading if systems contradict each other? Can we trace where data comes from? Is it clear which data an agent may use in which situation?
Those are perhaps less exciting questions than building a new AI agent, but they ultimately determine whether such an agent can function reliably.
Perhaps we should start less with the agent
The temptation is great to build a new agent for every problem immediately.
A sales agent, a service agent, a marketing agent, a finance agent, and an HR agent. Every department gets its own applications and every team builds its own connections with data.
That may work in initial experiments, but in the long run, a new problem arises.
Each agent has to figure out again where the right information is, which database is leading, and which customer identities should be linked together.
In doing so, you are essentially creating a new form of technical debt.
The alternative is to pay more attention to a shared context layer on which multiple agents can function.
A foundation in which identity, data sources, authorizations, and reliability are already settled and on which various AI applications can build.
This ultimately makes new agents not only more reliable, but probably also much faster to develop.
The smarter AI becomes, the more important the foundation
There lies perhaps the greatest paradox of agentic AI.
The more advanced the technology at the top of the organization becomes, the more important the seemingly traditional disciplines beneath it become.
Data modeling, Master Data Management, identity resolution, metadata, data lineage, governance, and security may sound less spectacular than autonomous agents and multi-agent systems.
But without those components, the intelligence of AI remains limited by the chaos of the information on which that AI must work.
An agent can be incredibly smart and still make the wrong decision when it has the wrong customer in front of it.
It can reason perfectly based on a contract that has since expired.
It can formulate an excellent answer based on information belonging to another person.
The model can, in all those cases, do exactly what it was designed for.
The problem then lies not in the intelligence.
The problem lies in the foundation.
The organizations that win, therefore, do not only build AI agents
The organizations that get the most out of agentic AI in the coming years will likely not simply be the companies with the smartest models or the most agents.
They will be organizations that succeed in combining AI with a reliable data foundation.
Organizations that know who their customers are, even when those customers are spread across multiple systems. Organizations that know which sources are reliable and can dynamically assemble context when an agent needs it.
And organizations that do not only think about what AI is allowed to do, but also about what information AI is allowed to use for that and how decisions can be audited afterwards.
That is ultimately where the true competitive advantage arises.
Not from AI alone.
But from the combination of AI, data, context, and governance.
Conclusion: don't just build the intelligence, also build the reality underneath it
There is currently a lot of justified enthusiasm about agentic AI. The technology can fundamentally change processes and enable organizations to organize work in a completely different way.
But anyone who only looks at the agent is missing an important part of the story.
An AI agent must know who it is talking about. It must understand where information comes from, which data is reliable, and how different data are interconnected.
That doesn't make the data foundation less relevant in the AI era.
It makes it more important than ever.
The most important challenge for organizations therefore becomes not only building intelligent agents, but creating an information environment in which those agents can operate reliably.
Because in the end, a simple rule applies:
the smarter the agent becomes, the better the reality underneath it must be organized.
That is likely what the next phase of agentic AI will be about.
Job van den Berg is an AI keynote speaker, tech entrepreneur and author of five books on AI. He ships AI agents into production every week and delivers 150+ keynotes a year on AI agents and agentic commerce.
Top brain, workhorse or sprinter? Choose the right AI model for each task and balance quality, speed and cost with smart AI-agent orchestration.
AI can accelerate archive research, but it can also invent missing facts convincingly. How to combine the right model, strict instructions and critical verification for reliable genealogy research.
GPUs do the model math, CPUs keep the rest of the agent running. Why agentic AI shifts the view of data centers, and what that means for Intel, AMD and organizations deploying agents.
What are open weights and closed-source AI models? Discover the differences and the consequences for costs, privacy, data centers and the AI market.